ScaleNav: Scalable Internet Video Pretraining for Language-Conditioned Local Navigation
Learning navigation priors from Internet videos through action-free pretraining, then transferring them to robot action generation.
Hi! I am an undergraduate student in Information Engineering at Zhejiang University. I will pursue my Ph.D. under the supervision of Prof. Xiaowei Zhou.
My research interests lie in embodied intelligence. I am currently exploring how robotic manipulation policies can adapt dynamically and generalize rapidly to new objects and environments.
Learning navigation priors from Internet videos through action-free pretraining, then transferring them to robot action generation.
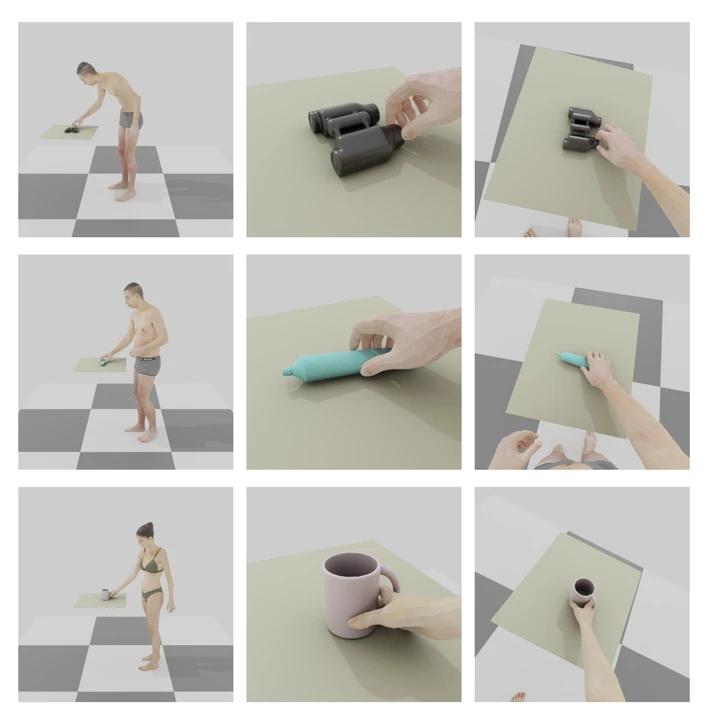
Autoregressive grasping motion generation from egocentric RGB images, combining visual features, body poses, and viewing directions.
Object-centric 4D scene understanding: separating interacting people and objects over time to enable consistent dynamic scene decomposition and editing.
Research Intern · Embodied Intelligence
World models and language-conditioned visual navigation